

 Developer platform
 Plugins and MCP
How does it work? (at a glance)
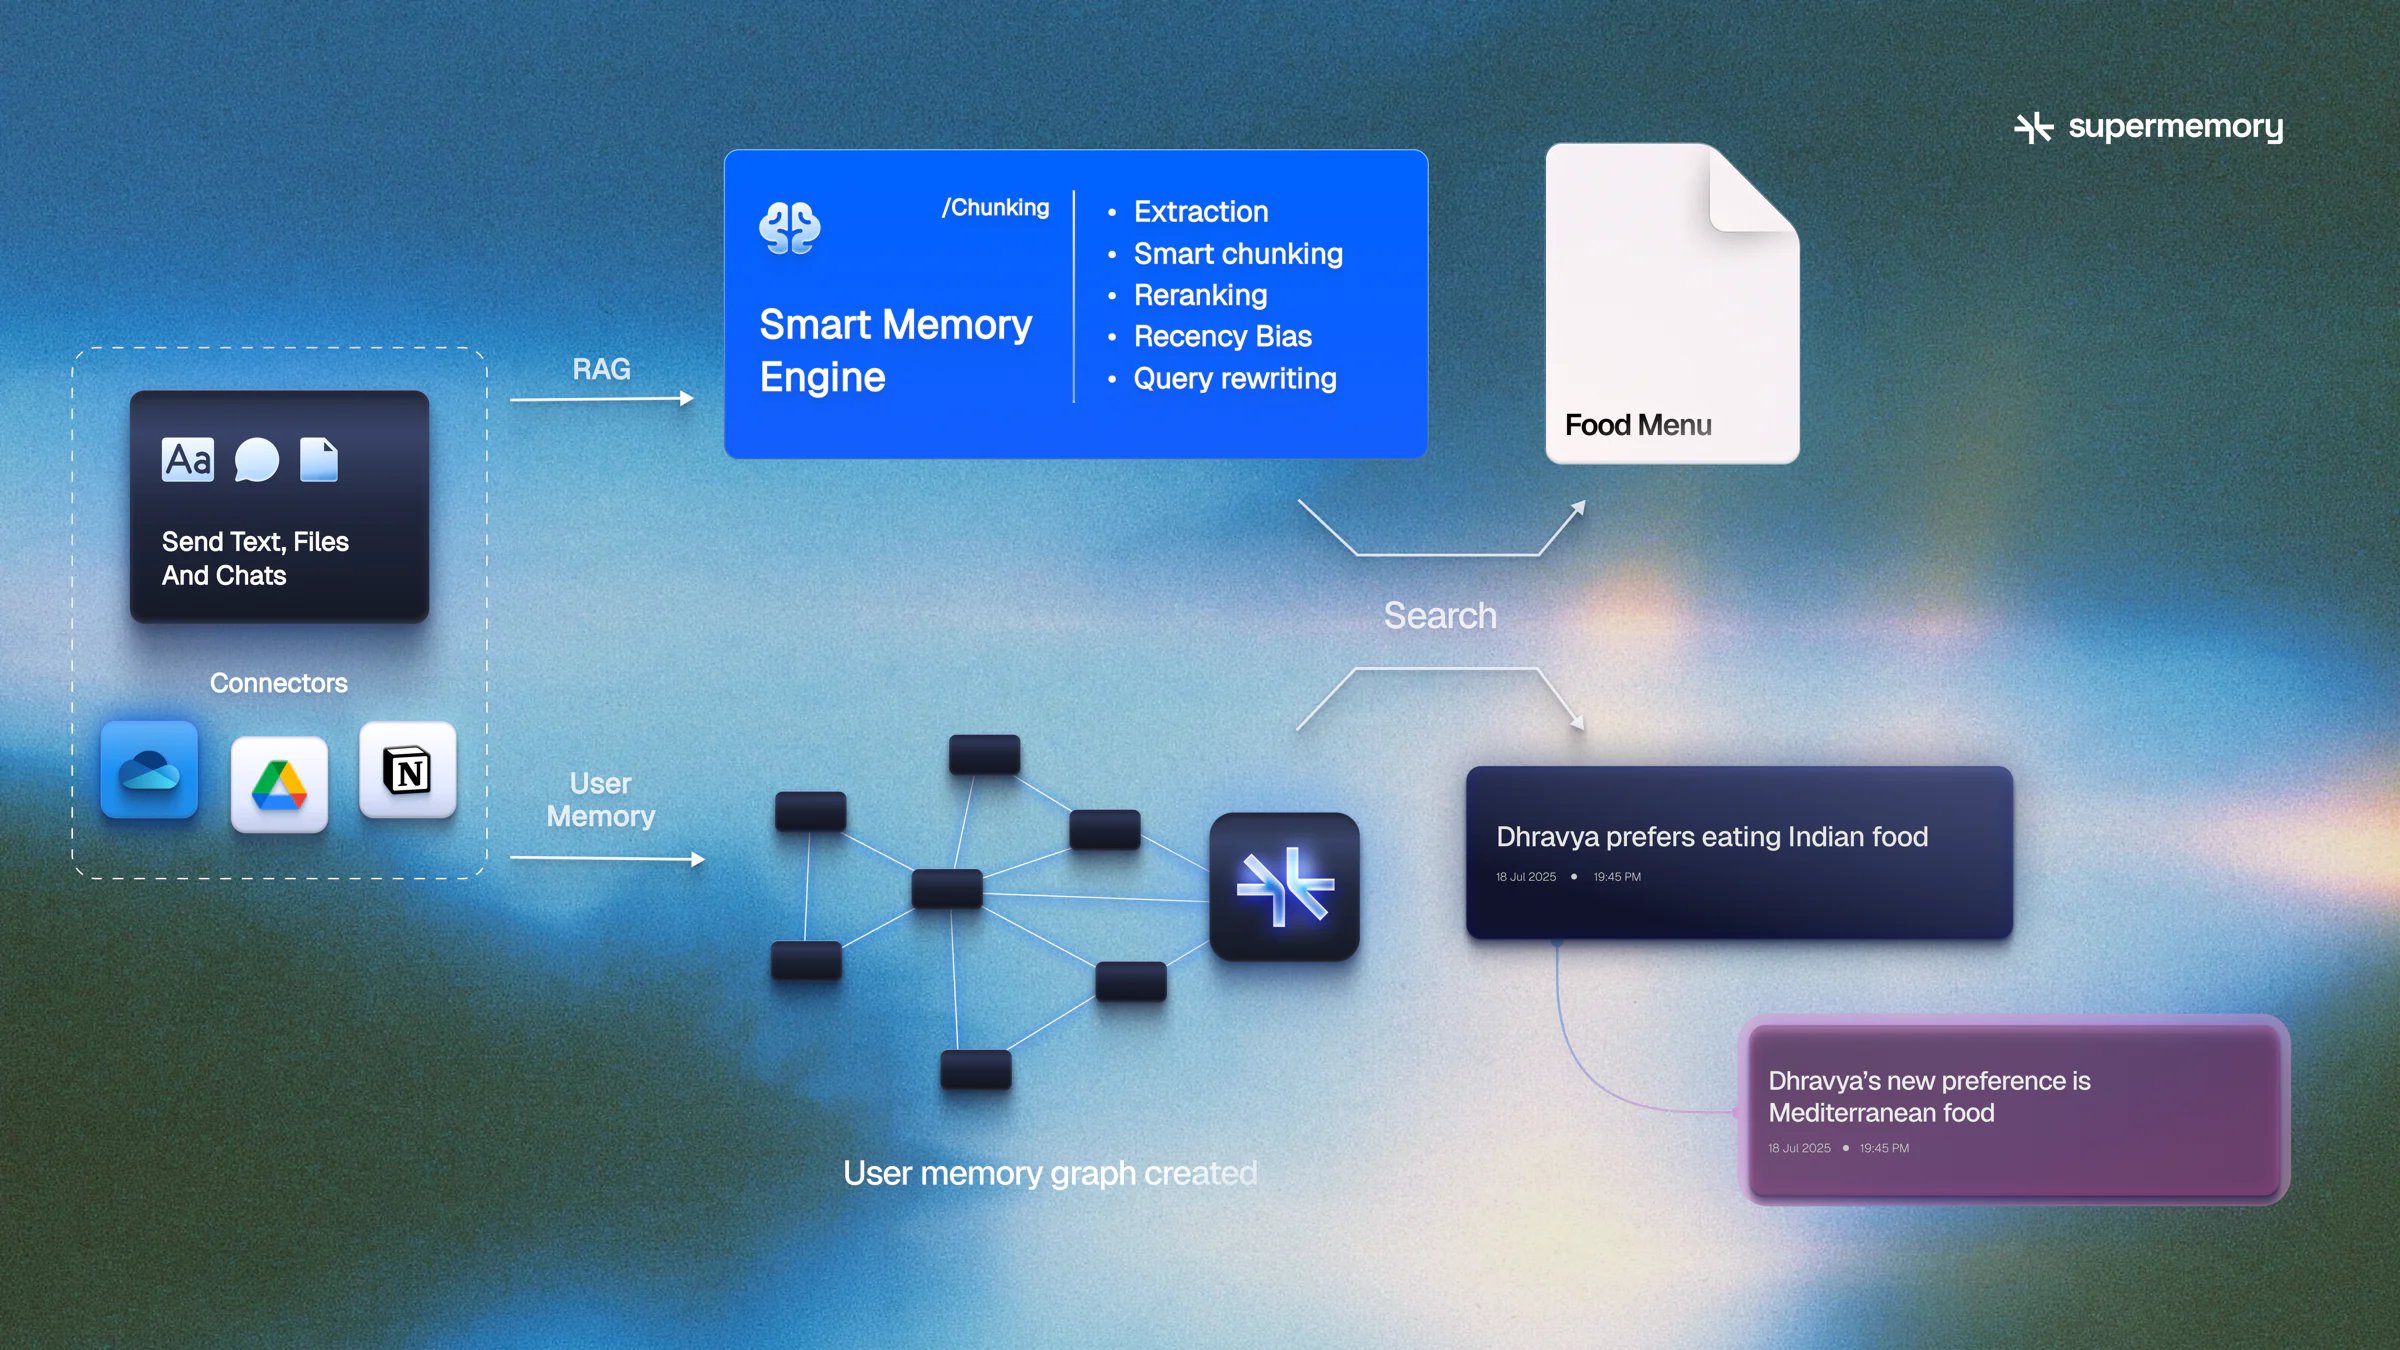
- You send raw data in any format (text, files and chats), or connect a data source.
- Supermemory indexes it and builds a graph of what it learns about each entity: a user, a document, a project or an organization. Each entity is identified by a
containerTag. - Your agent searches that graph for memory or retrieval, and Supermemory keeps a profile of each entity up to date.
Why add memory to your agent?
Without memory, every session starts from zero. The model cannot know what the user preferred last week, which project they are on, or that a fact has changed since yesterday. Memory gives an agent a lasting understanding of people and entities over time: their preferences, decisions, relationships and corrections. Retrieval (RAG) grounds answers in documents and knowledge bases. Most agents need both. With memory, your agent can:- Personalize answers with preferences, roles and history from earlier sessions, without putting the whole chat log in every prompt.
- Stay correct when facts change. If a user says “I love Adidas” and later “I’m switching to Puma”, only the newer preference should hold.
- Pull the right policy, ticket or document when a question needs source material.
- Keep each customer’s memory separate, so one user’s data never leaks into another’s.
Why Supermemory?
- It leads long-horizon memory benchmarks. First on LongMemEval, LoCoMo and ConvoMem, and strong on independent benchmarks like SWEContext.
- Memory is a graph. Facts update, connect and expire in real time instead of sitting as nearest-neighbor chunks.
- User profiles are built in. Static and dynamic facts about each user are ready to drop into the prompt.
- Memory and RAG share one engine. Personalization and document search run on the same
containerTag. - Every entry point uses one store. The API, MCP, plugins, SMFS and connectors all read and write the same memories.
- It is multimodal by default. Text, chats, PDFs, images, video and code are extracted automatically, whether you upload them or sync them.
- It runs where you need it. Use the managed cloud, or self-host a single binary that also works offline.
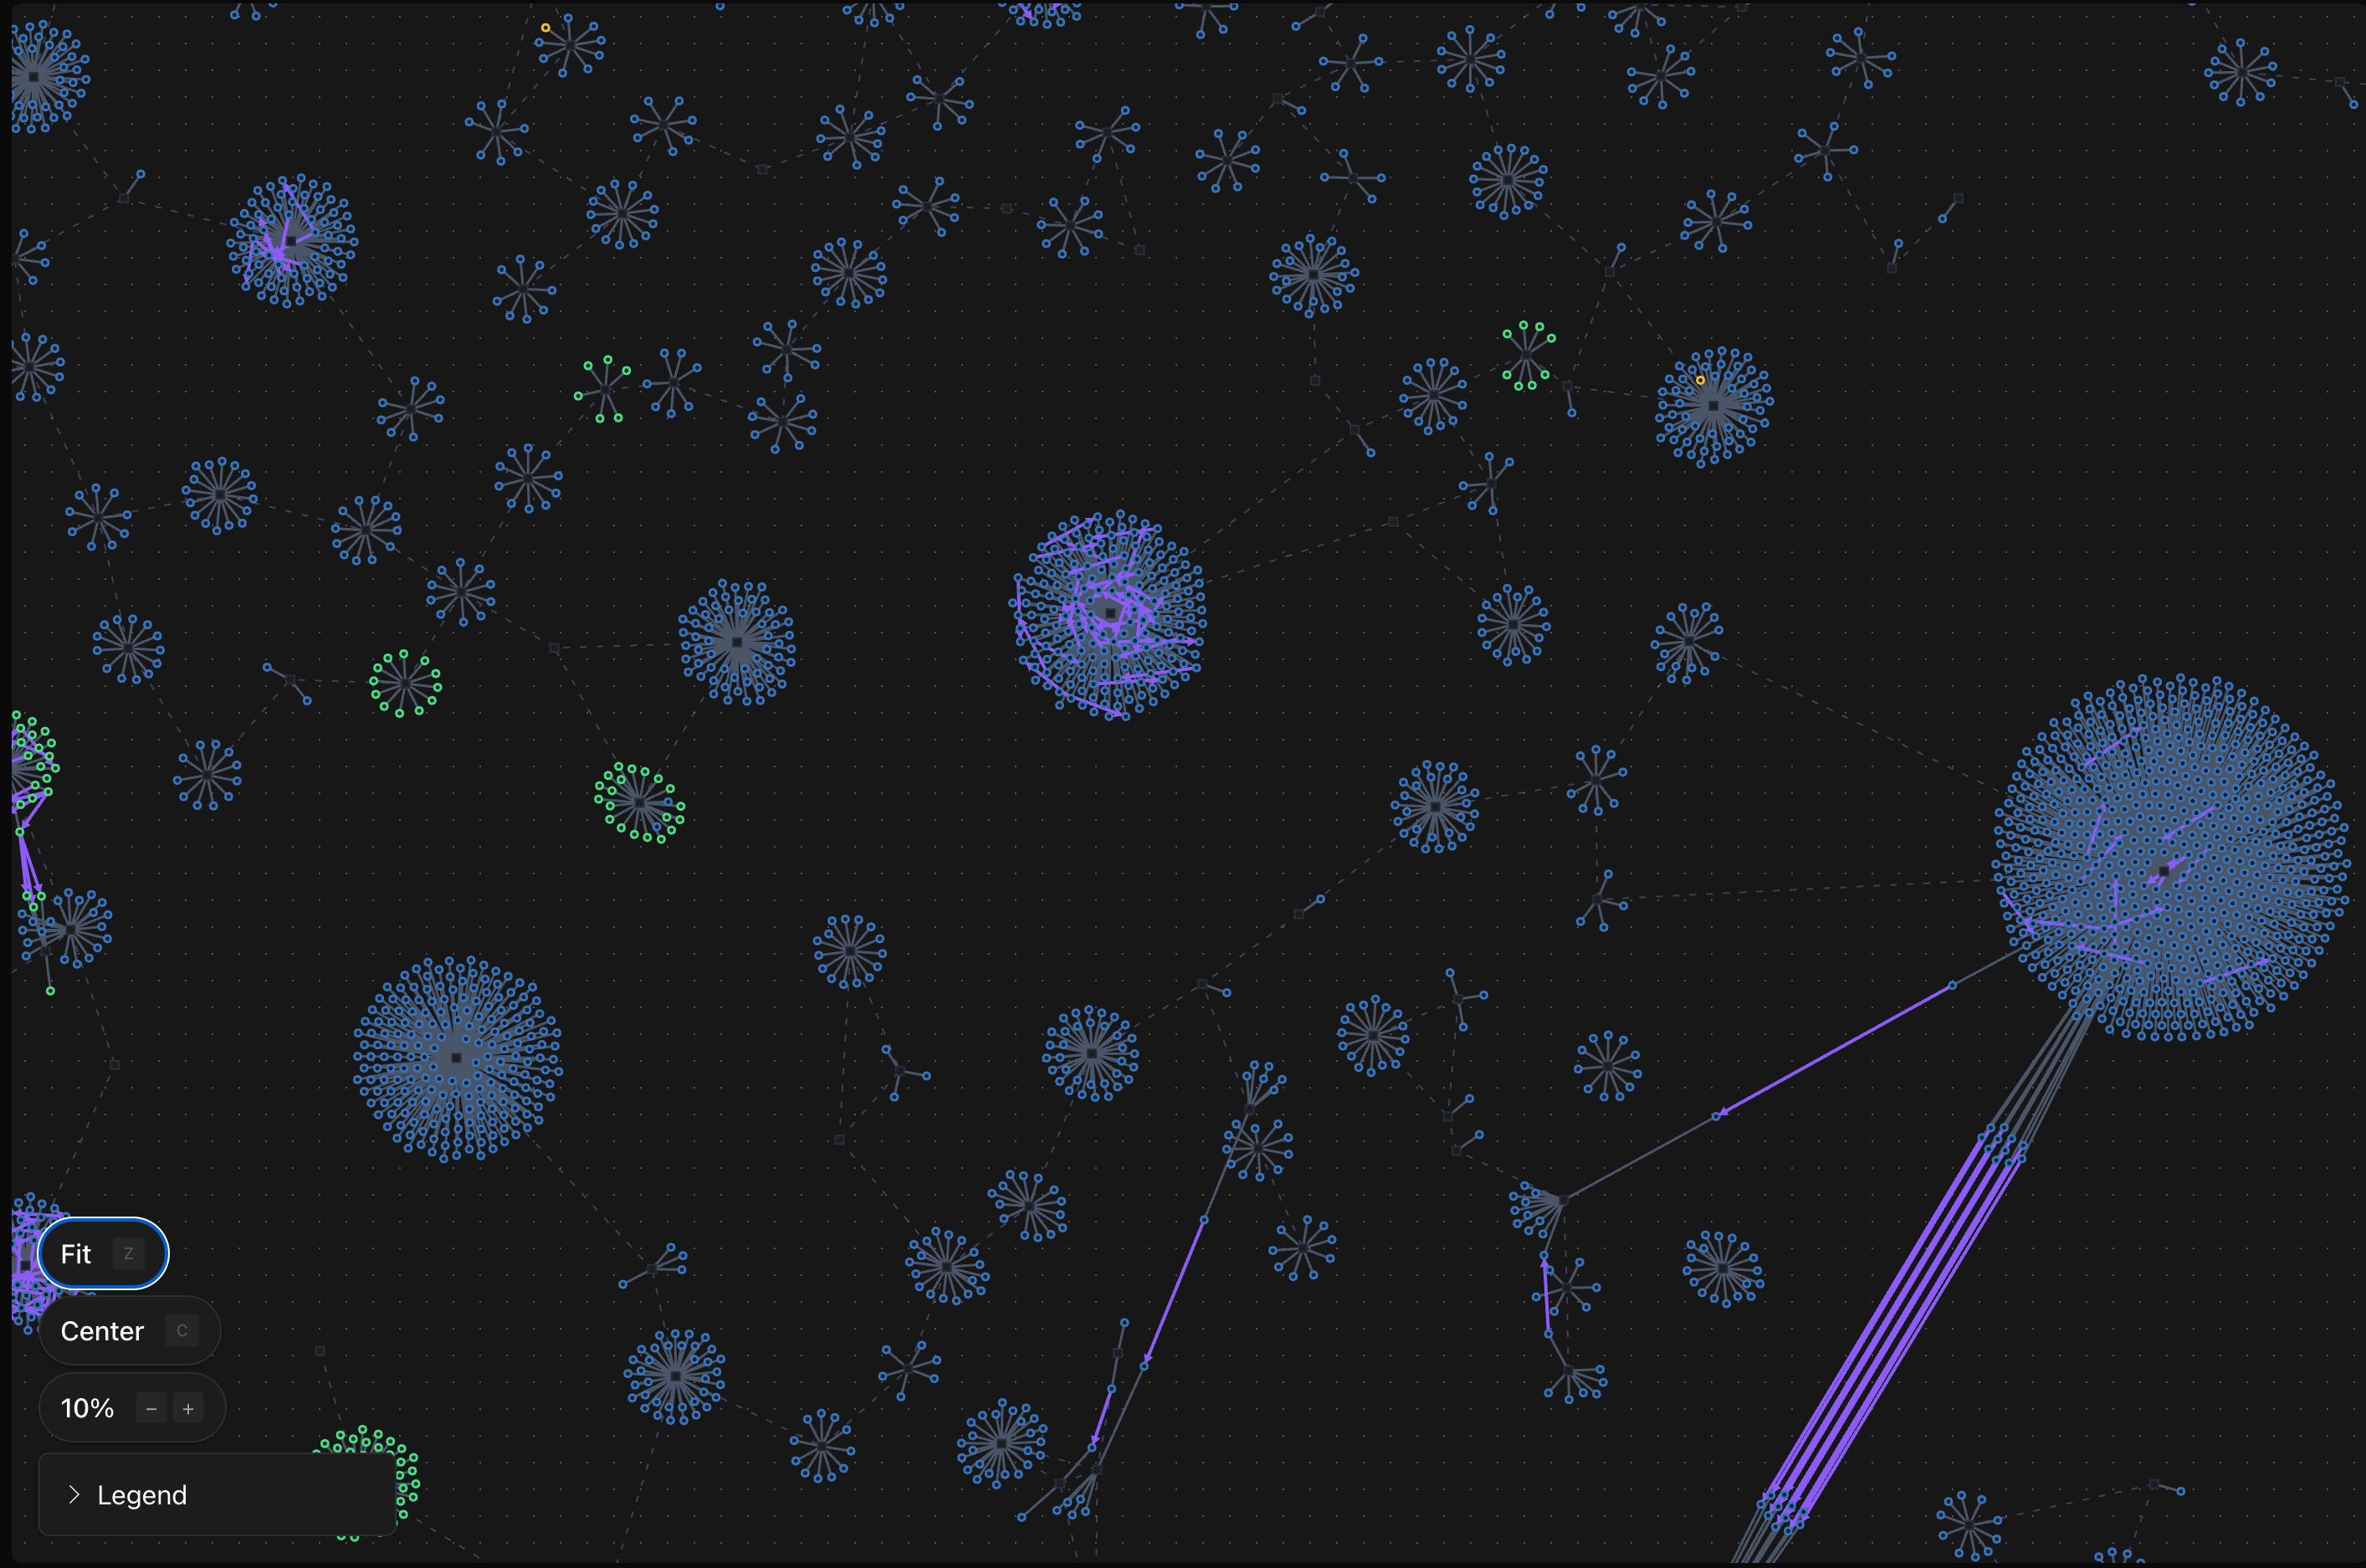
Memory, profiles and SuperRAG share one context pool when they use the same
containerTag. A container can be any scope you choose: a user, a project, a team or an organization.Next steps

Quickstart
Make your first API call in minutes

How it works
Understand the knowledge graph architecture

Comparison
vs DIY vectors, thin memory layers, pure RAG

Self-host it
One binary, zero config, fully offline

Billing & plans
Credits, SM tokens, and how usage works

Security & compliance
SOC 2, GDPR, HIPAA BAA, encryption